Rethinking Probability-Based Reinforcement Learning From Posterior Concentration
arXiv preprint, 2026
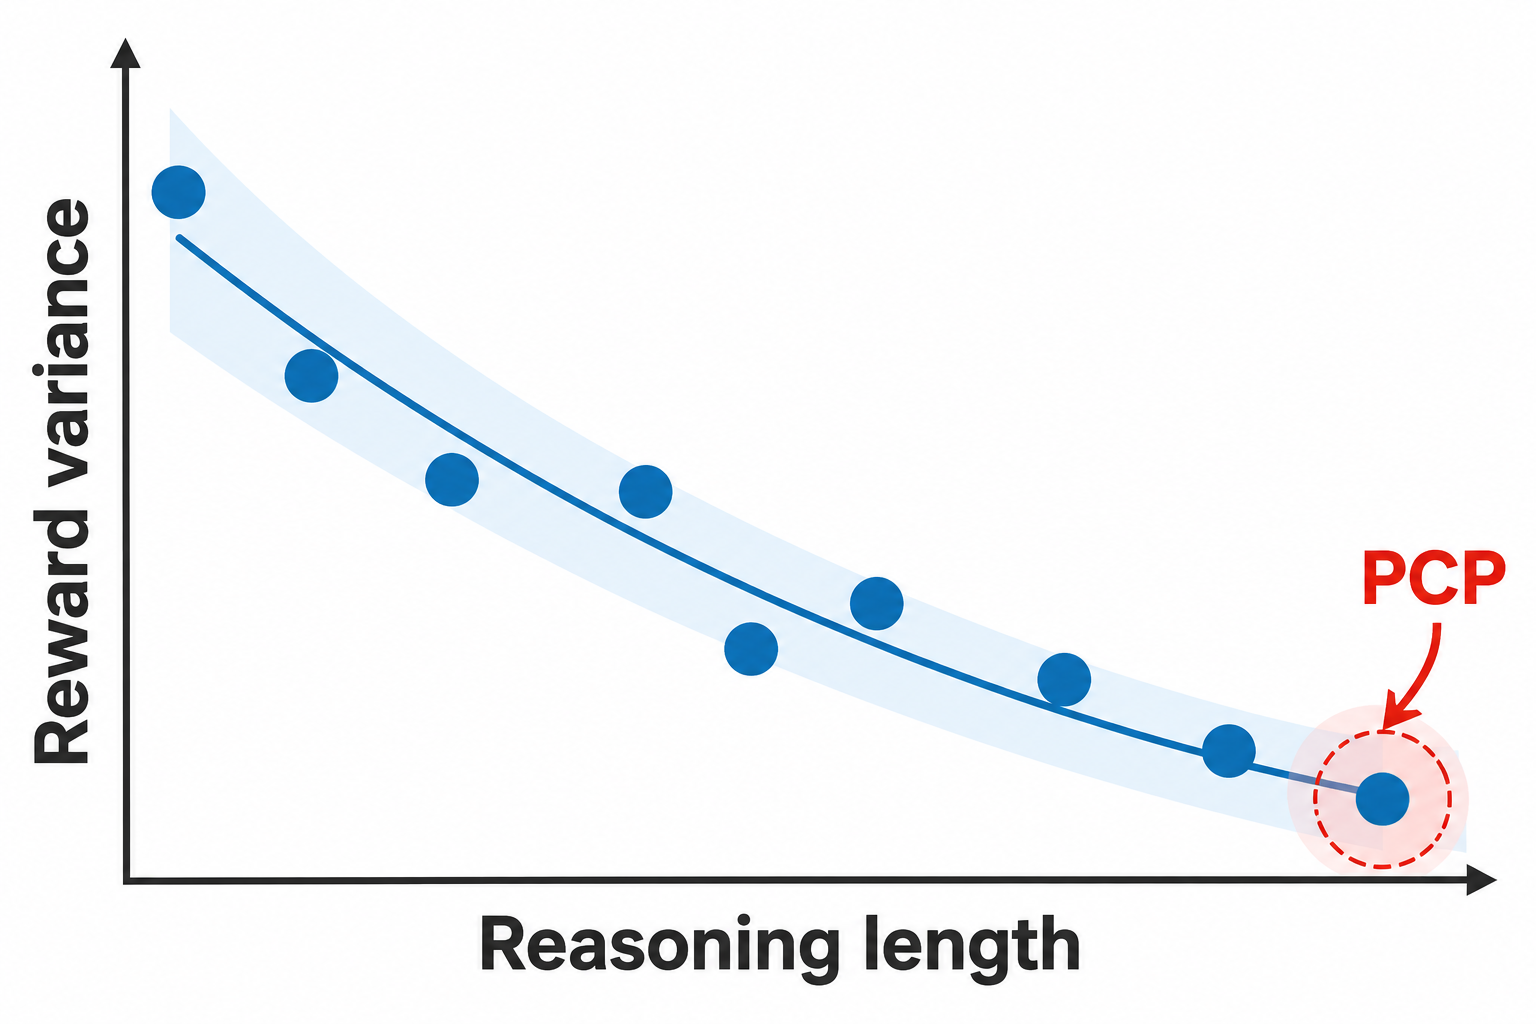
We identify the Posterior Concentration Phenomenon (PCP) in probability-rewarded long-horizon reasoning and propose RLCPR, a verifier-free RL framework that improves optimization stability, accuracy, and token efficiency.